ResilientCloudInfrastructure.ResilientCloudInfrastructure.
Auto-scaling cloud architectures, containerized Docker microservices, and multi-region automated failovers. Engineered for enterprises that cannot afford a single second of operational downtime.
Stop worrying about server crashes. We engineer cloud systems that heal themselves.
When servers go down during a critical business day, the financial losses and reputational damage are severe. We replace fragile single-server setups with resilient, containerized multi-node topologies.
Our DevOps engineers configure automated health checks, automated restart policies, and seamless blue-green deployments so that updating your software never requires kicking active users off the platform.
Zero-Downtime Rolling Deployments
Ship new features and security patches in the middle of a business day without taking your servers offline.
Automated Multi-Cloud Snapshots
Your entire database and file storage is replicated across isolated cloud providers with point-in-time recovery.
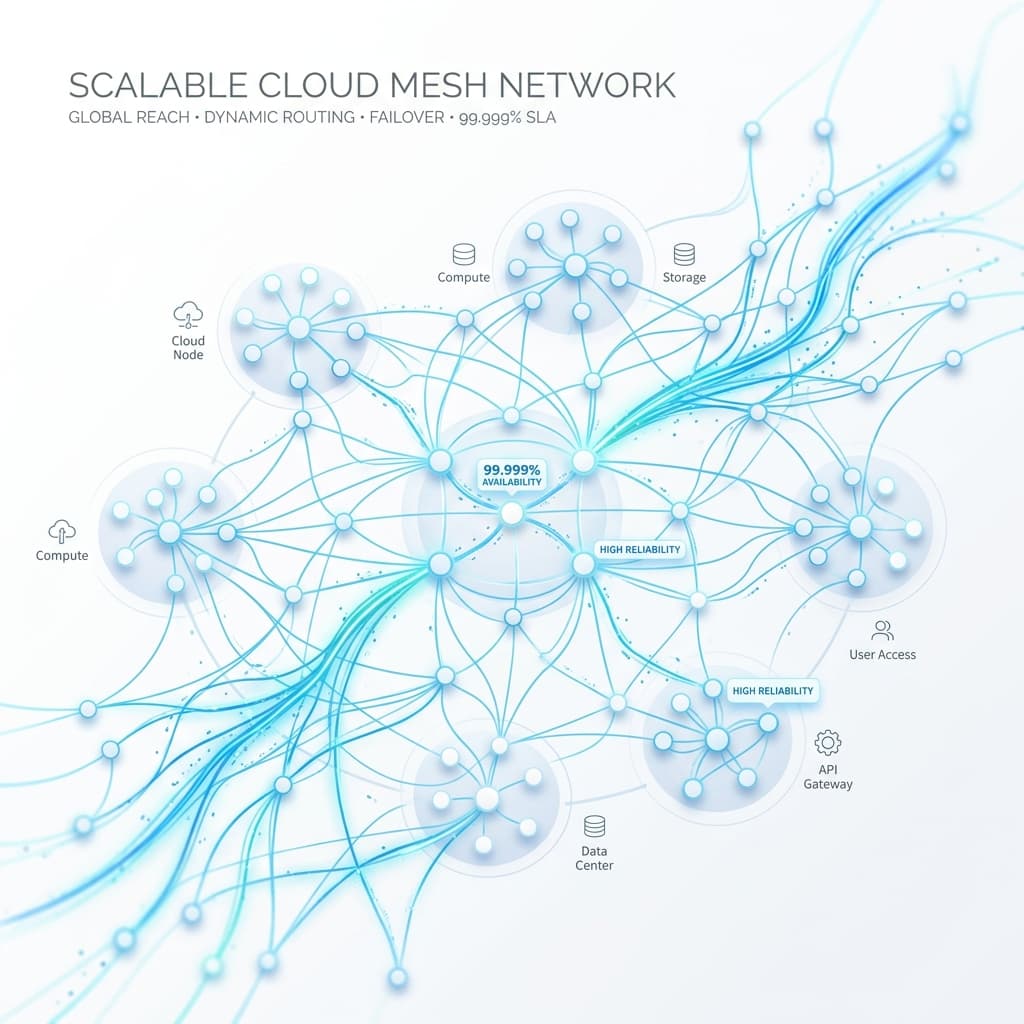
Engineered for 99.99% Availability
We combine industry-standard containerization, geographic redundancy, and proactive monitoring to ensure uninterrupted service.
Multi-Region Automated Failover
Single-data-center deployments are fragile. We configure active-passive and active-active geographic routing so if an AWS, Google Cloud, or DigitalOcean region suffers an outage, traffic reroutes in seconds with zero data loss.
Predictive Auto-Scaling
Traffic spikes shouldn't crash your servers or inflate your cloud bills. We implement horizontal pod auto-scalers that provision container resources dynamically during demand peaks and scale down to zero waste during off-hours.
Immutable Infrastructure as Code (IaC)
Every VPC, firewall rule, load balancer, and container configuration is documented in version-controlled Terraform and Docker Compose scripts, allowing complete environment recreation in minutes.
Automated Continuous Backups & Snapshots
Daily automated database dumps with cryptographic checksums stored in geographically isolated S3 cold storage. Point-in-time recovery ensures your business can restore to any second of any day.
Full-Spectrum Cloud & DevOps Services
Private VPS & Hybrid Cloud Deployment
Save up to 65% compared to bloated public cloud bills. We architect high-performance bare-metal and private VPS clusters tailored for local and national enterprises.
Containerization & CI/CD Pipelines
Standardize your runtime environments with Docker. We build automated GitHub Actions pipelines that test, lint, and deploy code with zero human intervention.
Database Replication & Read Replicas
Offload intensive reporting and analytics queries to dedicated asynchronous read-replica databases, keeping master transactional write pools instantaneous.
DDoS Mitigation & Edge Firewalls
Implement enterprise Cloudflare web application firewalls (WAF), rate-limiting, and bot management at the edge, blocking malicious attacks before they ever reach your servers.
Cloud Infrastructure FAQ
Why is a multi-region cloud setup better than a single cloud server?
A single cloud server is vulnerable to hardware failures, regional fiber cuts, and provider-level downtime. A multi-region architecture distributes traffic and mirrors databases across geographically distinct data centers, guaranteeing that your application remains fully operational even if an entire region goes offline.
How does Easyio prevent massive, unexpected cloud bills from AWS or Google Cloud?
Many companies suffer from 'cloud bill shock' due to unoptimized egress bandwidth, oversized virtual machines, and unmanaged database instances. We right-size compute instances, implement aggressive Redis caching, utilize private VPS and bare-metal nodes where appropriate, and set up hard automated spending limits.
What is your Recovery Time Objective (RTO) and Recovery Point Objective (RPO)?
For critical enterprise deployments, we target an RPO of under 60 seconds (maximum possible data lag in a catastrophic disaster) and an RTO of under 5 minutes for full automated failover to replica infrastructure.
Can you manage and monitor our cloud infrastructure 24/7?
Yes. Easyio provides comprehensive infrastructure management SLAs, including real-time Prometheus and Datadog monitoring, automated incident alerting, security vulnerability patch updates, and guaranteed response times.
Scale Your Cloud with Confidence
Let our certified cloud architects audit your infrastructure, optimize costs, and build a high-availability deployment plan.